Product Overview

A quick look at the GLYNT.AI solution

Audit-Ready Sustainability Data

Prepared for ISSA 5000 and other audit standards

Sustainability Data Layer

Works with the software and AI you already use

Approval Workflows for Sustainability Data

Four-Eyes review for audit compliance

Finance-Grade Sustainability Data

The same rigor as financial data

Integrate with Financial Data

Reconcile against your financial ledger

AI-Ready Sustainability Data

See what’s missing or flagged before deadlines

Powered by Green AI

Built for low energy use and emissions

Best Practices for Sustainability Data Management

Manage data instead of wrangling it

Enterprise Security

Privacy, security, and controls

Sustainability Data Accuracy

We test your data so you don’t have to

Comprehensive File Capture

Extract data from scans, portals, and messy formats

Customized Reporting

See what’s missing or flagged before deadlines

Audits & Assurance

Traceable data, approval workflows with SOC compliance

Business Value Add

Customize output files for CSRD, IFSR, CBAM, UKSRS

Energy Data Management

Granular data for transparency and cost reductions

Waste Data Management

Pull files from everywhere, send data to anywhere

Scope 3 & PCFs

Stop chasing suppliers, move to finance-grade quality

Blog

What’s new with GLYNT

Customer Stories

Industry applications for GLYNT solutions

Guides

GLYNT’s expertise and thought leadership

Conquer Document Variety with GLYNT

by | Oct 23, 2019

Almost every workflow begins with a document, or actually many documents. And that is where the trouble begins. Current solutions deliver the data from one document type, but require months of work to do simple data matching from a range of documents. They can’t handle the variety of documents found in modern enterprise workflows.

That’s why we’re delighted to announce our new White Paper, “How to Conquer Document Variety in Enterprise Workflows: The Power of AI with Very Little Data,” which takes an in-depth look at how GLYNT conquers data extraction when a multitude of document types are streaming in.

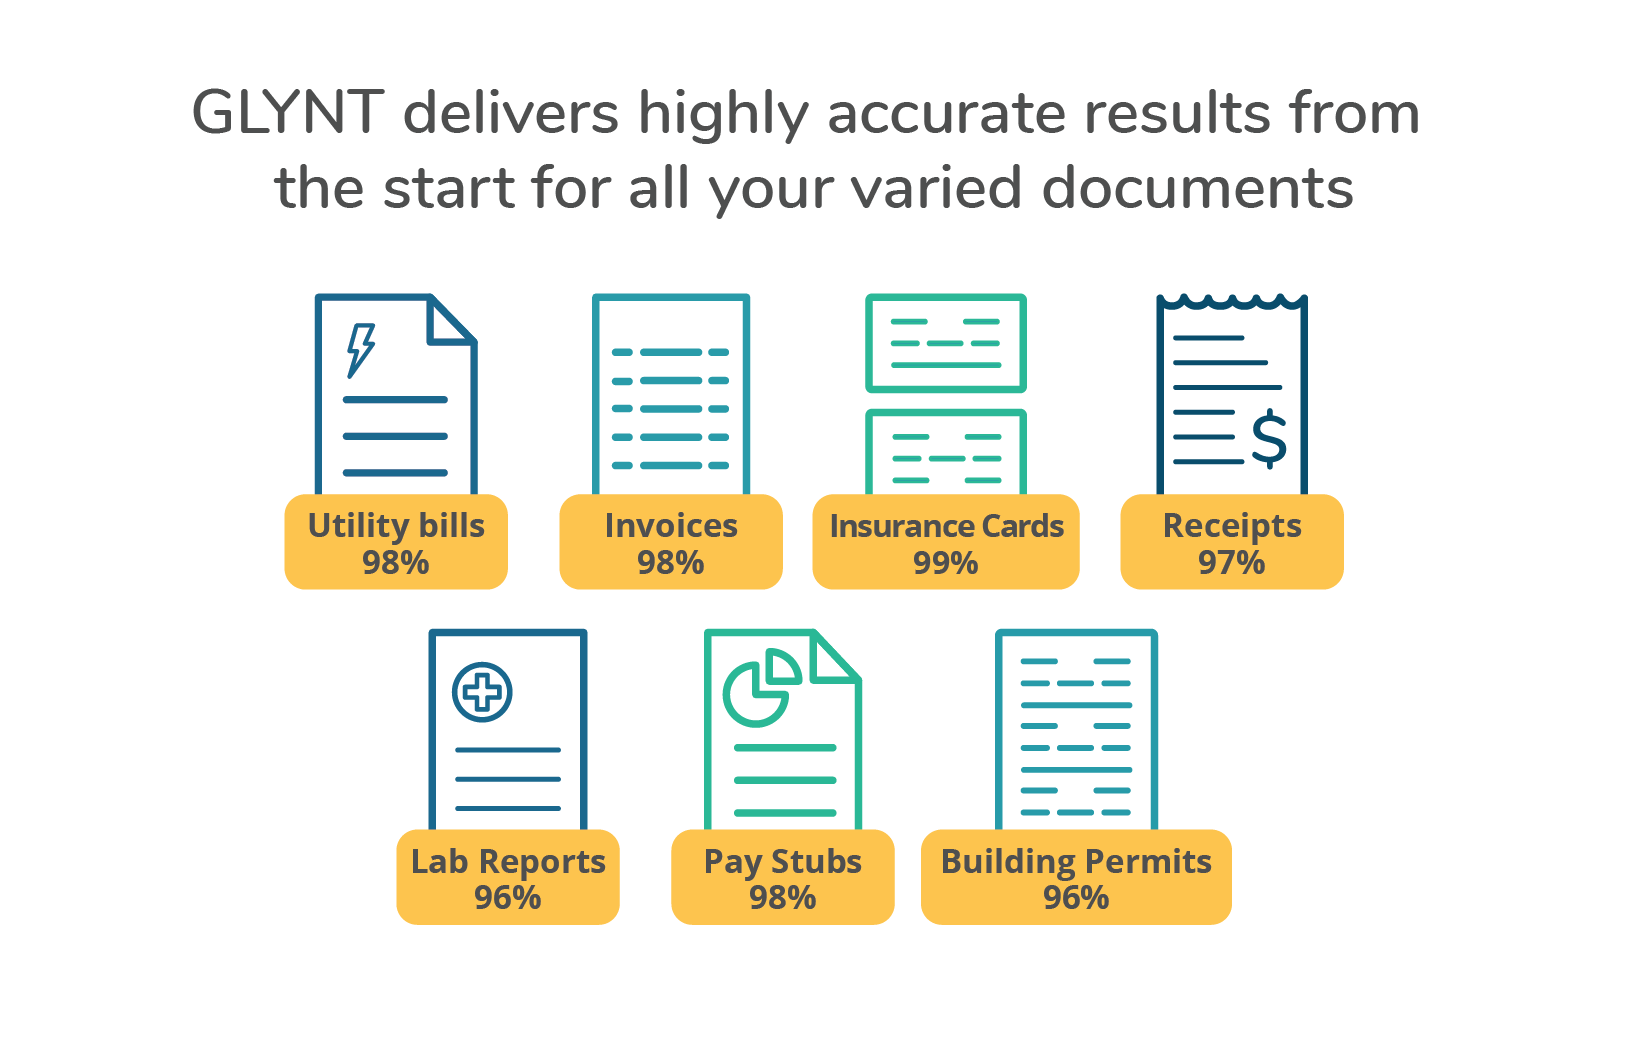
Here’s a sneak peek at how AI with Very Little Data works: GLYNT is based on a unique machine learning (ML) system that customizes data extraction in minutes, averaging 98% accuracy from the start. Once the ML models are set up, GLYNT automatically routes incoming documents to the right model.

Get started in minutes, deploy to production in days. Speed your document flow. Reduce your errors. That’s GLYNT!

Read the white paper here.

Ready to see more? Contact GLYNT for a product demo today!