
Product Overview

A quick look at the GLYNT.AI solution

Audit-Ready Sustainability Data

Prepared for ISSA 5000 and other audit standards

Sustainability Data Layer

Works with the software and AI you already use

Approval Workflows for Sustainability Data

Four-Eyes review for audit compliance

Finance-Grade Sustainability Data

The same rigor as financial data

Integrate with Financial Data

Reconcile against your financial ledger

AI-Ready Sustainability Data

See what’s missing or flagged before deadlines

Powered by Green AI

Built for low energy use and emissions

Best Practices for Sustainability Data Management

Manage data instead of wrangling it

Enterprise Security

Privacy, security, and controls

Sustainability Data Accuracy

We test your data so you don’t have to

Comprehensive File Capture

Extract data from scans, portals, and messy formats

Customized Reporting

See what’s missing or flagged before deadlines

Audits & Assurance

Traceable data, approval workflows with SOC compliance

Business Value Add

Customize output files for CSRD, IFSR, CBAM, UKSRS

Energy Data Management

Granular data for transparency and cost reductions

Waste Data Management

Pull files from everywhere, send data to anywhere

Scope 3 & PCFs

Stop chasing suppliers, move to finance-grade quality

Blog

What’s new with GLYNT

Customer Stories

Industry applications for GLYNT solutions

Guides

GLYNT’s expertise and thought leadership

The Disappearance of the “Bad Scan”

by | Sep 15, 2021

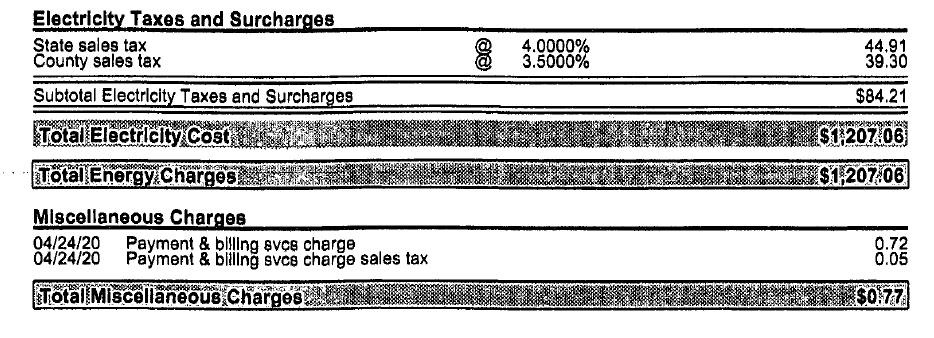
Two years ago, a GLYNT customer sent us thousands of scanned utility bills. It was as if someone had been standing at a scanner for hours, putting stacks of bills through the machine. But, they forgot to clean the glass plate or think about the settings. So we got a stack of very pixelated, coarse and sometimes skewed images. A snippet is below.

And our machine learning struggled because the OCR engine struggled. For example, take a look at the line labeled Total Electricity Cost. It’s got black font on a gray background, with a line underneath the words. At that time the OCR engines often failed to see the black font. Or they got confused between the line and the text and would pull out the line instead of the text. And there would be character errors, such as the ‘$’ in the cost amount turning into an ‘S’.

As a result, GLYNT accuracy rate for the stack of scanned documents was in the 65 – 70% range. The GLYNT computer vision team did some document enhancements to correct for the bad scanner, and after weeks of work, our accuracy rose to nearly 80%.
But today the situation is entirely different. The OCR engines available have improved enormously. Black font on a grey background – no problem. Document skew – typically no problem. Confusion around lines – almost never. Today GLYNT’s accuracy on these scans is in the high 90%, not much lower than the rate on clean PDFs.

As you can see, GLYNT’s advanced machine learning (ML) is dependent on the OCR engine. If the OCR can’t see a word, the ML can’t process it. And if the OCR sees the text with an error, it weakens the ML results. Our solution is to bring in all of the world-class OCR engines – AWS, MSFT, GOOG, and Abbyy. Typically we use AWS, but when needed the other OCR engines are available for testing too.

So the bad scan has largely disappeared! The upgraded OCR engines are not perfect, and some documents are still problematic. If you have that stack of scanned documents, send them over. They may be gems after all.